TL;DR
- Halfsies 1.3.0 was split into work packages, and each package went to its own AI agent with a written brief and a test.
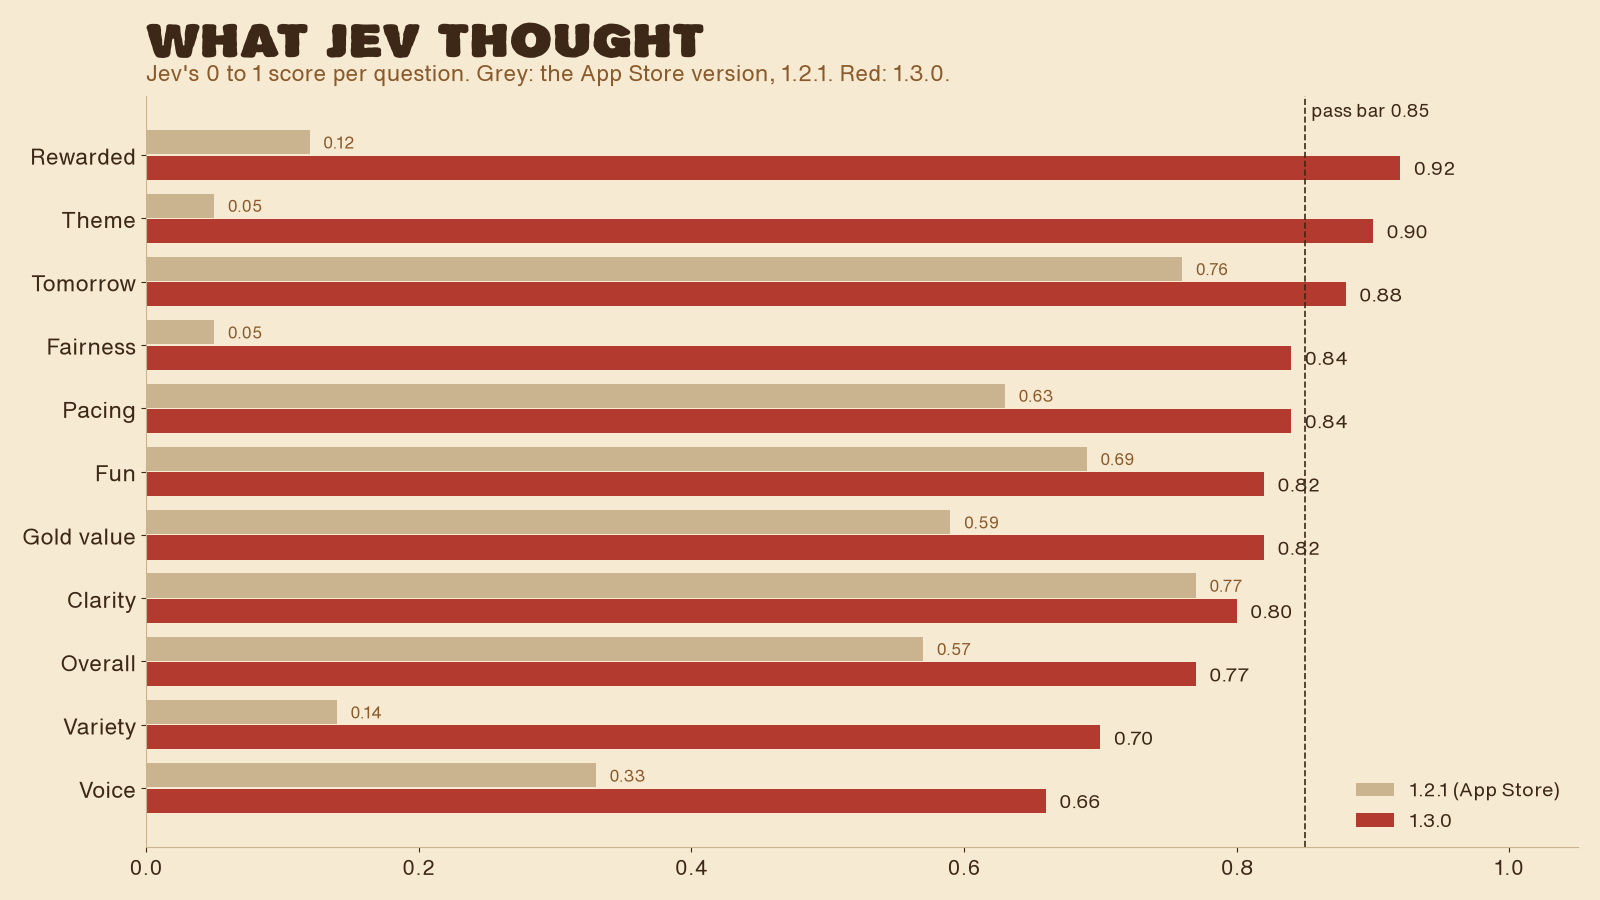
- Jev, a judge model, plays four days of the real game through scripted players and scores 11 questions from 0 to 1.
- The App Store version scored 0.46. After 12 build-and-judge rounds the best build scored 0.82.
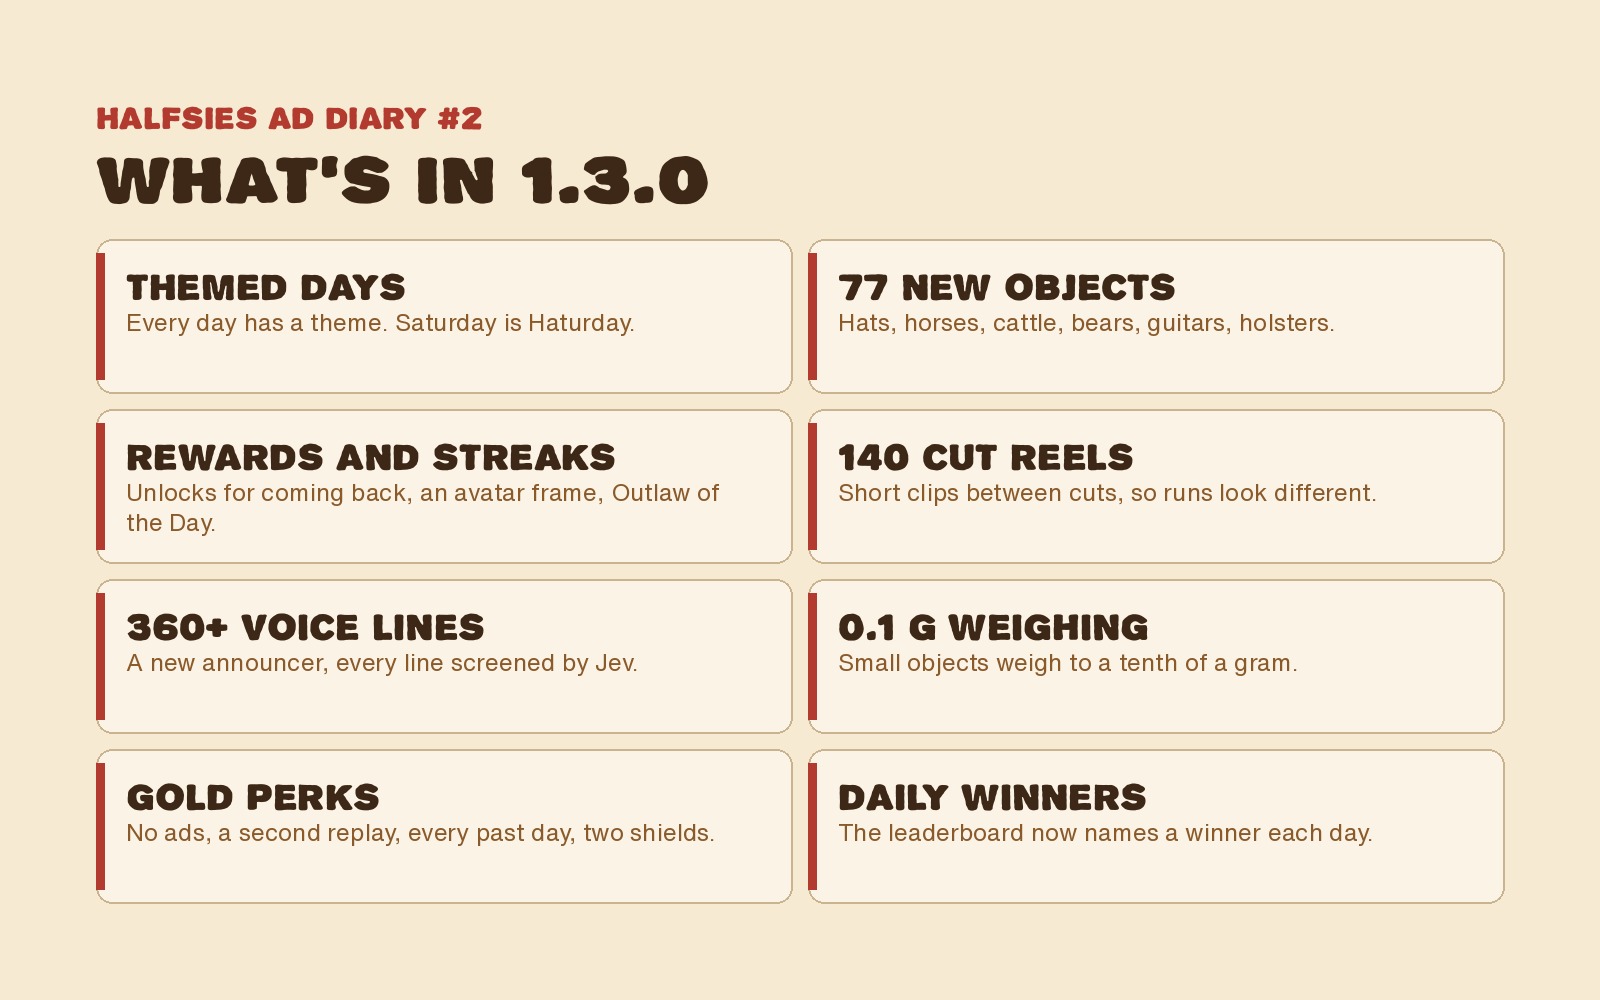
- The big jumps came from fixing what Jev called unfair or empty: weighing to 0.1 g, themed days and rewards.
- Voice and variety are still the weakest answers, and they lead the next update.
Halfsies is my daily cutting game for iPhone. Three objects, one cut each, and a brass scale weighs the halves. Version 1.3.0 is the biggest update since launch, and almost all of it was built by AI agents and checked by a judge model. The Jeje Studios diary for that day covers the update and the ads. This is how the build worked, and what actually moved the score.
One agent per job
Claude split the update into work packages: weights and the scale, cut reels, the calendar of themed days, rewards, the leaderboard, Gold, voice lines and the screens that tie it together. Each package went to its own agent with a written brief and a test it had to pass. Separate review agents checked the work before it was merged.
I kept the calls that need a person. I chose the Gold perks, set the contest rules and gave the go-ahead to submit. Everything else ran through briefs, tests and reviews.
A judge that plays the game
Jev is a judge model I calibrated for Halfsies. Scripted players run the real game in a phone-sized browser for four days of puzzles. Jev reads everything that happened and answers 11 fixed questions, each from 0 to 1. Is it fun? Does it feel fair? Do you want to come back tomorrow? Does the voice fit?
The fixed questions are the point. The agents can't argue with a number, and a weak answer turns straight into the next brief.
0.46 to 0.82 in 12 rounds
I ran Jev on the App Store version first. It scored 0.46. Then the loop started: agents build, Jev judges, the weakest answers go back to the agents. After 12 rounds the best build scored 0.82.
| Question | 1.2.1 | 1.3.0 | What moved it |
|---|---|---|---|
| Rewarded | 0.12 | 0.92 | Hats, badges, an avatar frame and an Outlaw of the Day |
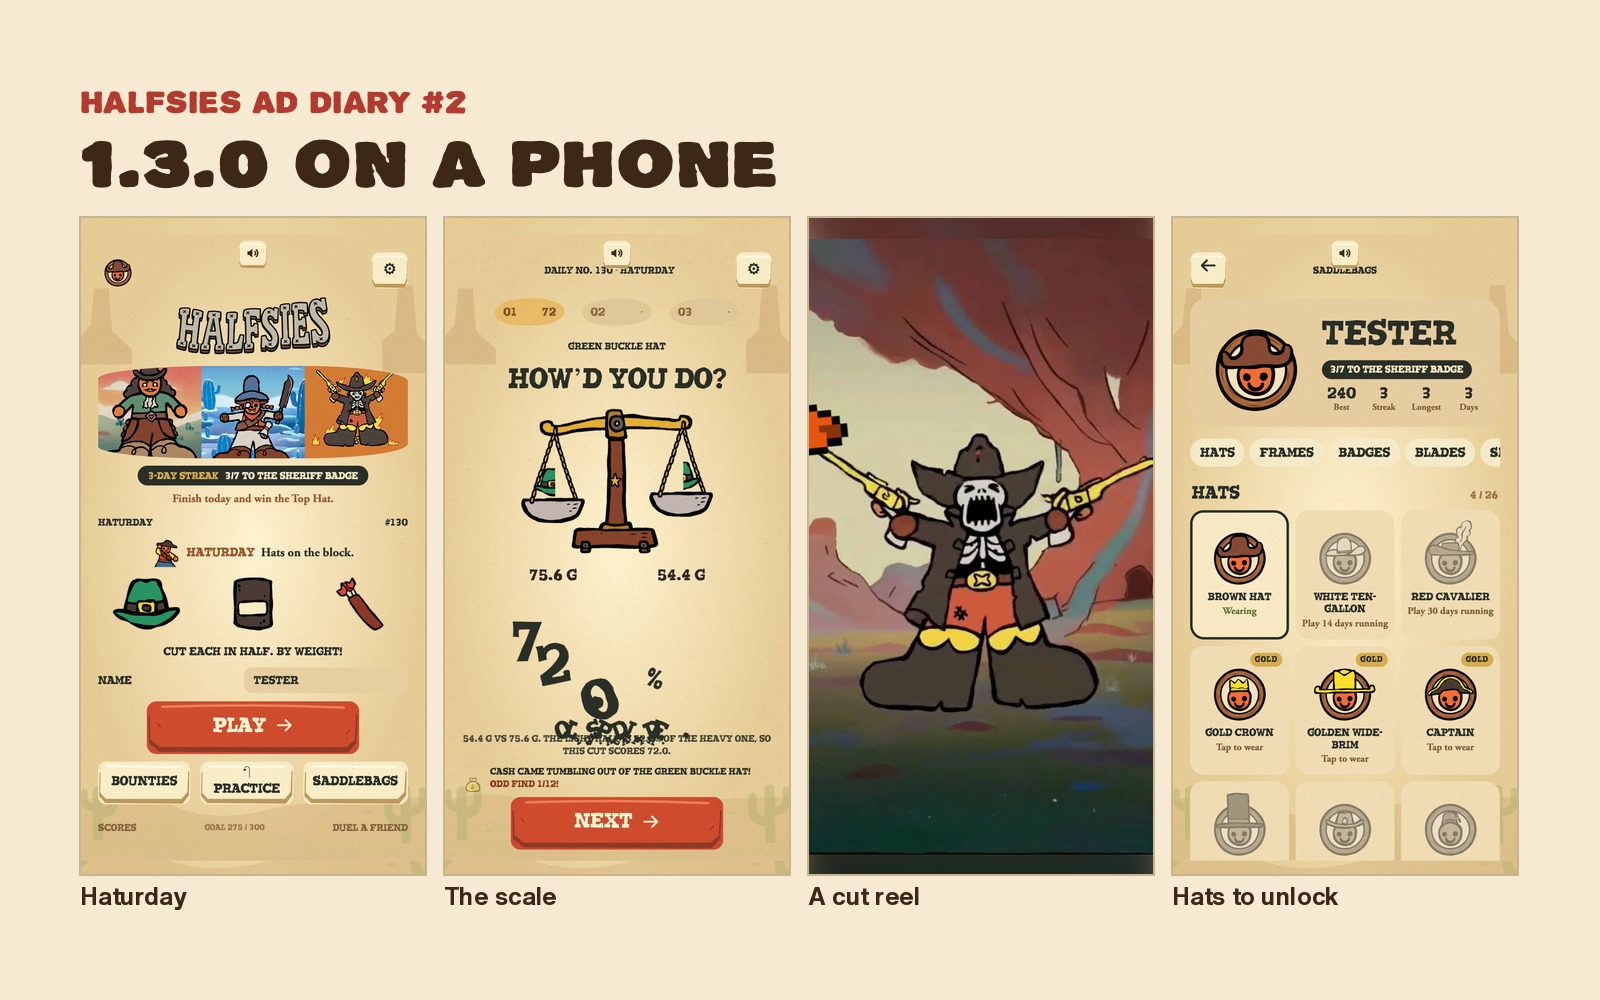
| Theme | 0.05 | 0.90 | A theme for every day of the week, like Haturday |
| Fairness | 0.05 | 0.84 | Light objects weighed to a tenth of a gram |
| Variety | 0.14 | 0.70 | 77 new objects and 140 cut reels |
| Weighted score | 0.46 | 0.82 | 12 rounds of build and judge |
Fairness is my favourite line in that table. On the old scale a close cut on a small hat could read as a miss, and Jev scored fairness 0.05. Weighing to 0.1 g took it to 0.84. One change to the scale did more than any new screen.
Shipping at 0.82
Jev's own pass bar is 0.85 on every question, and 1.3.0 doesn't clear it everywhere. Voice scored 0.66 and variety 0.70, because a few announcer lines and some cut reels came round too often in one run. The last check before submission came in at 0.81. I set the bar for shipping at anything over 0.80, and sent it.
Waiting for a perfect score would have held back everything that already worked. The repeat problem leads the next update, and the cut reels and voice lines have their own write-up.
What I'd keep
- Write the questions before the build starts, and don't change them between rounds.
- Make the judge play the real game, not read the code.
- Feed the lowest answer back as the next brief.
- Decide your shipping bar up front, and keep the human calls human.
Halfsies 1.3.0 is submitted to the App Store. The game is free at halfsies.jejestudios.com, and the latest Jeje Studios diary tracks where it stands.